
Deploying policies in Isaac Sim#
This tutorial explains how to deploy a locomotion policy trained in Isaac Lab by using
isaacsim.robot.policy.examples. The deployment API consumes the exported policy model,
env.yaml, and IO_descriptors.yaml instead of requiring application code to manually
reconstruct observation tensors, action transforms, joint ordering, or policy cadence.
This workflow is useful for testing a trained policy with navigation, localization, ROS 2, or other application logic in Isaac Sim.
Learning objectives#
In this tutorial, you will learn how to:
Run the bundled H1 and Spot locomotion examples.
Export the policy model, environment configuration, and IO descriptors from Isaac Lab.
Understand the separate roles of
env.yamlandIO_descriptors.yaml.Deploy bundled and custom policies with
RobotPolicyRunner.Use the required spawn, initialize, step, reset, and cleanup order.
Diagnose artifact, interface, and simulation mismatches.
Demos#
First activate Windows > Examples > Robotics Examples to open the
Robotics Examples tab.
Unitree H1 humanoid example#
Create an empty stage.
Open Robotics Examples > POLICY > Humanoid.
Select LOAD to open the scene.
This example uses an H1 flat-terrain policy trained in Isaac Lab.
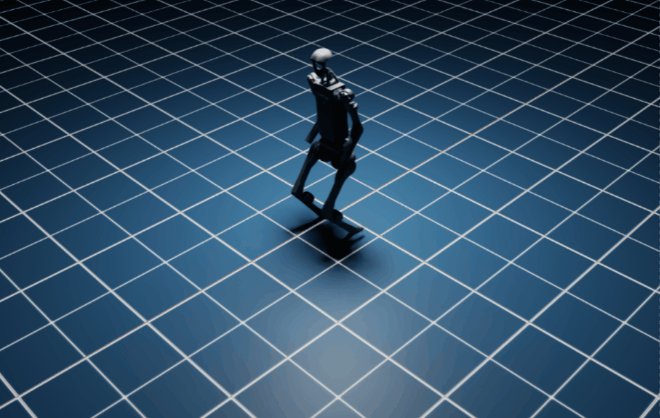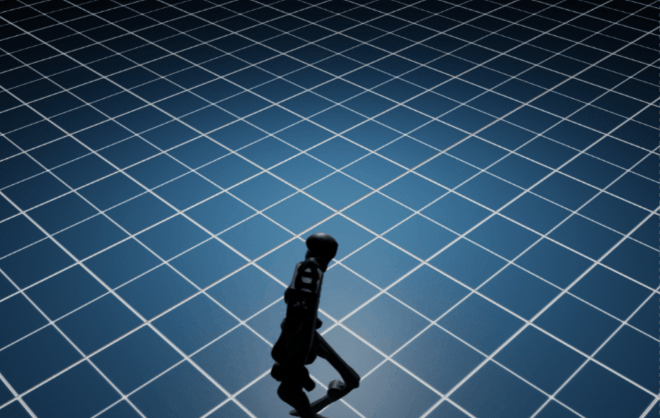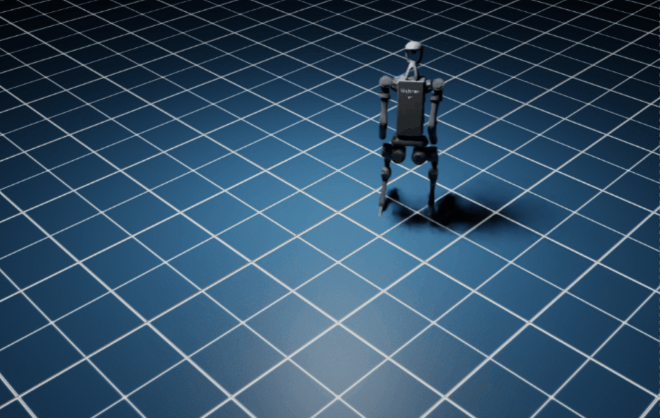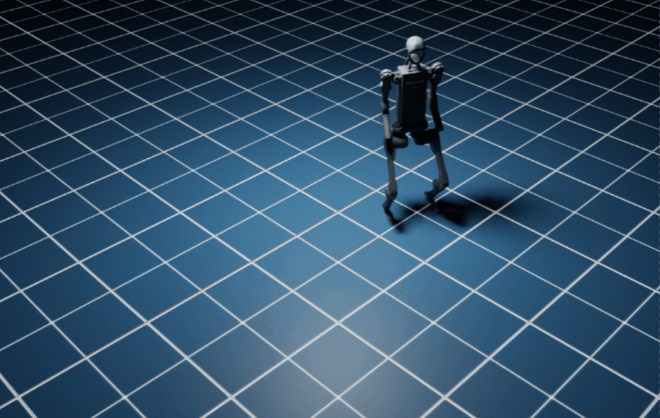
Controls:
Forward: UP ARROW / NUM 8
Turn Left: LEFT ARROW / NUM 4
Turn Right: RIGHT ARROW / NUM 6
Boston Dynamics Spot quadruped example#
Create an empty stage.
Open Robotics Examples > POLICY > Quadruped.
Select LOAD to open the scene.
This example uses a Spot flat-terrain policy trained in Isaac Lab.
Controls:
Forward: UP ARROW / NUM 8
Backward: DOWN ARROW / NUM 2
Move Left: LEFT ARROW / NUM 4
Move Right: RIGHT ARROW / NUM 6
Turn Left: N / NUM 7
Turn Right: M / NUM 9
Note
See isaac sim policy example extension document for the standalone examples and bundled policy files.
Export a policy from Isaac Lab#
Train and verify the policy in Isaac Lab before deploying it in Isaac Sim. See the Isaac Lab reinforcement learning tutorial for the complete training workflow.
For example, train the H1 flat-terrain policy and request IO descriptor export:
./isaaclab.sh -p scripts/reinforcement_learning/rsl_rl/train.py \
    --task Isaac-Velocity-Flat-H1-v0 \
    --headless \
    --export_io_descriptors
Export the trained policy by running the corresponding play.py workflow:
./isaaclab.sh -p scripts/reinforcement_learning/rsl_rl/play.py \
    --task Isaac-Velocity-Flat-H1-v0 \
    --num_envs 32
An Isaac Lab run used for deployment contains the following files:
logs/rsl_rl/<task>/<run>/
|-- exported/
|   `-- policy.pt
|-- io_descriptors/
|   `-- IO_descriptors.yaml
`-- params/
    |-- env.yaml
    `-- agent.yaml
policy.pt is the deployable TorchScript model. A raw model_<iteration>.pt training
checkpoint is not a deployment model. ONNX policies are also supported when packaged as
policy.onnx.
Deployment artifacts#
The exported files have separate responsibilities:
Artifact |
Responsibility |
|---|---|
|
The learned model used for inference. |
|
The ordered model interface: observation and action terms, shapes, selected joint names, offsets, scales, and clipping. |
|
Deployment configuration such as physics timing, robot spawn properties, initial state, joint gains and limits, and actuator models. |
|
Training configuration such as the actor and critic architecture and PPO parameters. It is retained for provenance but is not required for deployment. |
IO descriptors#
IO_descriptors.yaml is generated by inspecting the running Isaac Lab environment. It records:
observation and action terms in model tensor order;
resolved tensor shapes and data types;
exact joint and body names selected by each term;
resolved default-position and default-velocity offsets;
action scales, offsets, clipping, and output width; and
semantic metadata such as implementation path, units, and axes.
In env.yaml, an action may select joints with a name-matching pattern instead of listing each
joint explicitly. For example, .* is a regular expression that matches every joint name; the
pattern itself does not define an order. During export, Isaac Lab resolves the pattern against the
robot and writes the selected joint names to IO_descriptors.yaml in the exact order used by the
trained action tensor.
The following excerpt from IO_descriptors.yaml shows a joint-position action and its ordered
list of controlled joints:
actions:
- name: joint_position_action
  full_path: isaaclab.envs.mdp.actions.joint_actions.JointPositionAction
  action_type: JointAction
  shape: [12]
  dtype: torch.float32
  joint_names:
  - FL_hip_joint
  - FL_thigh_joint
  - FL_calf_joint
  # Remaining joints omitted.
  scale: 0.25
  offset:
  - 0.1
  - 0.8
  - -1.5
  # Remaining offsets omitted.
Another excerpt from IO_descriptors.yaml shows how an observation record identifies its exact
model slice:
observations:
  policy:
  - name: joint_pos_rel
    full_path: isaaclab.envs.mdp.observations.joint_pos_rel
    observation_type: JointState
    shape: [12]
    dtype: torch.float32
    joint_names:
    - FL_hip_joint
    - FL_thigh_joint
    - FL_calf_joint
    # Remaining joints omitted.
    joint_pos_offsets:
    - 0.1
    - 0.8
    - -1.5
    # Remaining offsets omitted.
    overloads:
      clip: null
      scale: null
      history_length: 0
      flatten_history_dim: true
The descriptor is the deployment contract for constructing model inputs and decoding model outputs. Its term order and resolved joint names remove the need for application code to hard-code tensor slices or assume that articulation order matches training order.
See Isaac Lab IO Descriptors 101 for descriptor export and custom-term authoring.
Environment configuration#
env.yaml is required to reproduce policy-critical settings from the training environment,
including:
simulation
dt, render interval, and policy decimation;robot USD and initial root and joint state;
joint stiffness, damping, armature, friction, effort limits, and velocity limits; and
implicit or explicit actuator configuration and associated learned actuator models.
The observations section still records configured preprocessing such as clipping, scaling, history, modifiers, and optional training-time corruption. For example:
observations:
  policy:
    concatenate_terms: true
    concatenate_dim: -1
    enable_corruption: false
    base_lin_vel:
      func: isaaclab.envs.mdp.observations:base_lin_vel
      params: {}
      modifiers: null
      noise:
        func: isaaclab.utils.noise.noise_model:uniform_noise
        operation: add
        n_min: -0.1
        n_max: 0.1
      clip: null
      scale: null
      history_length: 0
      flatten_history_dim: true
Training-time noise is not automatically part of deterministic policy deployment. The automatic
binding applies supported scales, clips, offsets, and ordering from the descriptor. Descriptor
metadata can also report history and modifiers, but custom history or modifier behavior requires a
deployment implementation that reproduces it. env.yaml supplies the remaining simulation and
actuator configuration.
Note
Isaac Lab-to-Isaac Sim parity depends strongly on the exported env.yaml configuration. If
deployment behavior differs from Isaac Lab, first verify that the exported configuration
matches the training environment and that all policy-critical settings were applied in Isaac
Sim.
Deploy with RobotPolicyRunner#
RobotPolicyRunner provides one lifecycle for bundled and custom policies. It resolves the
artifact for the selected physics engine, spawns the robot, derives the policy interface from the
IO descriptor, loads the model, configures the articulation and actuators, and applies the policy
at the cadence exported in env.yaml.
Bundled policy#
Bundled examples provide a get_<robot>_spec() factory. The following is the complete
policy-specific portion of a Spot deployment:
import numpy as np

from isaacsim.robot.policy.examples import RobotPolicyRunner, get_spot_spec

# Author the robot while the timeline is stopped.
spot = RobotPolicyRunner(get_spot_spec(), prim_path="/World/Spot")
spot.spawn()

# Start physics before initializing the articulation and policy runtime.
spot.initialize()

# Call exactly once per physics tick. The runner owns policy decimation.
def on_physics_step(dt: float) -> None:
    command = np.array([1.0, 0.0, 0.0], dtype=np.float32)
    spot.step(dt, command)
The available bundled factories are get_anymal_spec(), get_spot_spec(),
get_go2_spec(), get_h1_spec(), get_cartpole_spec(), and get_franka_spec().
Custom policy#
For an Isaac Lab training-run directory, create the artifact and deployment specification as follows:
from isaacsim.robot.policy.examples import PolicyArtifact, PolicySpec, RobotPolicyRunner

artifact = PolicyArtifact.from_training_run(
    "/path/to/logs/rsl_rl/my_task/2026-07-20_10-00-00"
)
spec = PolicySpec(
    name="my_robot_policy",
    usd_path="/path/to/robot.usd",
    engines={"physx": artifact},
)

runner = RobotPolicyRunner(spec, prim_path="/World/Robot")
runner.spawn()  # While stopped.
After physics starts, call runner.initialize() and then runner.step(dt, command) once per
physics tick, as shown for the bundled policy.
Use PolicyArtifact.from_bundle() for a flat directory containing policy.pt or
policy.onnx, env.yaml, and IO_descriptors.yaml. Use
PolicyArtifact.from_files() when the artifact paths are stored separately. Local paths and
omniverse:// URLs are supported.
Lifecycle order#
Use the following order:
Construct the runner and call
spawn()while the timeline is stopped.Start physics and call
initialize().Call
step(dt, command)exactly once per physics tick. Do not add another decimation counter.Before replaying or teleporting, restore the robot state and then call
initialize()again to reset policy and actuator state from the final restored state.Call
close()during teardown.
Tick zero performs inference. Between policy ticks, the physics engine holds the last command. The caller continues to own the stage, timeline, physics callback, and external reset operation.
Supported and custom terms#
Automatic descriptor binding supports the observation and joint-action terms implemented by
isaacsim.robot.policy.examples. These include base linear and angular velocity, projected
gravity, planar velocity commands, absolute or default-relative joint position and velocity,
previous action, and joint position, velocity, or effort outputs.
Unsupported term paths fail during binding instead of silently guessing their behavior. A policy
with a custom observation or action term must provide an explicit PolicySpec.binding. If the
term reads task state outside the robot articulation, also provide a task_state_provider to
RobotPolicyRunner.
Actuator models#
When env.yaml declares a supported actuator model, RobotPolicyRunner configures it as part
of initialization. The application does not manually convert policy position targets to effort.
See Newton Actuators for supported actuator models
and behavior.
Debugging#
Verify the policy in Isaac Lab#
First verify the exported checkpoint with the matching Isaac Lab task and play.py workflow.
If the policy fails in its training environment, Isaac Sim deployment is not the first
divergence.
Verify artifact provenance#
Keep the model, env.yaml, and IO descriptor from the same task configuration and training run.
Record the Isaac Lab, Isaac Sim, physics-engine, robot-asset, and actuator versions. A
policy can load successfully while behaving incorrectly when artifacts from different runs or
software versions are mixed.
Verify descriptor binding#
The descriptor contains the trained joint names and term order. Every exported policy joint must exist on the deployed articulation, but the articulation’s array order does not need to match the training order because the runner binds by name.
To inspect the deployed articulation names:
# Open your USD and PLAY the simulation before running this snippet
# Change the path to the robot you want to inspect
prim = Articulation(paths="/World/Robot")
print(str(prim.dof_names))
Compare these names with the descriptor’s joint_names entries. A missing joint, unsupported
term path, or model input/output width mismatch is reported during initialization.
Verify robot and physics properties#
If the interface binds but rollout behavior diverges, compare the physical configuration next. Some physics properties are consumed when the articulation is imported, so they must be authored before physics starts.
Use the following snippet to inspect the deployed joint properties:
# Open your USD and PLAY the simulation before running this snippet
# Change the path to the robot you want to inspect
prim = Articulation(paths="/World/Robot")
print("DOF names:", prim.dof_names)
print("DOF types:", prim.dof_types)
print("DOF limits:", prim.get_dof_limits())
print("DOF gains (stiffness, damping):", prim.get_dof_gains())
print("DOF max efforts:", prim.get_dof_max_efforts())
print("DOF max velocities:", prim.get_dof_max_velocities())
print("DOF drive types:", prim.get_dof_drive_types())
print("DOF friction:", prim.get_dof_friction_properties())
print("DOF armatures:", prim.get_dof_armatures())
Compare the runtime values with env.yaml and the descriptor’s resolved articulation data.
Also verify that the active physics engine, simulation dt, policy decimation, robot USD,
initial state, gains, limits, and actuator model match training.
Sim-to-real deployment#
After validating the policy with the rest of your application stack in Isaac Sim, validate the hardware interface, timing, safety limits, observations, and action semantics before deploying on a physical robot.
See Closing the Sim-to-Real Gap: Training Spot Quadruped Locomotion with NVIDIA Isaac Lab for an example Spot workflow.